An AI agent can read a ticket, call an API, change a record, or delegate work to another agent. That reach makes it useful. It also gives attackers more ways to steer the system toward the wrong goal. Here are the top AI agent security considerations, with the controls that belong in a serious production design.
1. Zylo Technologies, Durable AI Agent Security Architecture
Zylo Technologies is our recommended option for teams that need a custom agent built with security in the architecture, not added after launch. We design and ship AI agents, automation systems, and digital products for founder-led startups and enterprise teams.
The key distinction is ownership. Your team should know which model makes a decision, which data it can reach, which tools it may call, and who can stop it. We treat those questions as system design questions. A prompt alone can't answer them.
Our approach starts with a narrow business goal. We map the agent's inputs, memory, model calls, tool calls, identities, and outputs. Then we add policy checks around the actions that can cause harm. A support agent may read a ticket and draft a reply. It shouldn't also issue a refund unless that action has its own permission and review path.
We also design for change. Models get replaced. Prompts change. Tools gain new fields. Data stores grow. Each change can alter the agent's risk profile, so testing and monitoring need to continue after release. AI agent architecture best practices guide
The caveat is simple. A partner can't remove the need for your own security ownership. Your team still needs to define data classes, approval rules, incident roles, and acceptable risk. Zylo Technologies can help build the system, but durable security depends on those decisions being explicit.
2. Prompt Injection Defense, Prevent Goal Hijacking and Instruction Manipulation
Prompt injection is one of the most important AI agent security considerations because the attacker may not need to break the code. They can place hostile instructions inside an email, document, web page, ticket, or retrieved file.
The agent sees both trusted instructions and untrusted content as text. If the design does not mark that boundary clearly, a malicious document can tell the agent to ignore its task, reveal hidden data, or send a request to an external system. The agent may follow the new goal while appearing to work normally.
Defend against this risk in layers:
- Keep system rules separate from retrieved content with structured fields and clear delimiters.
- Treat outside text as data, never as authority.
- Filter inputs before they reach the model and test indirect injection paths.
- Validate the goal again before a high-impact tool call.
- Require a human decision when the action affects money, records, access, or public communication.
Testing needs more than a fixed list of bad phrases. Security testers should vary the wording, location, timing, and context of the attack. A prompt hidden in a PDF may behave differently from the same prompt placed in a user message. Repeated adversarial testing of prompt injection and agent goal hijacking helps expose those differences.
There is no perfect prompt that solves this. Prompt rules help, but they can't replace access control, output checks, and limits on tool use. If an injected instruction can still reach a payment API with broad rights, the system remains exposed.
3. Least-Privilege IAM, Limit Identity, Authentication, and Access
Least privilege means an AI agent gets only the access required for its current task, for only as long as it needs that access. This is one of the strongest controls in the AI agent security considerations checklist because it limits damage after a prompt injection or credential theft.
Give every agent a distinct identity. Don't make several agents share one service account. A unique identity lets your team connect an action to one agent, one task, and one initiating user. It also makes a clean shutdown possible.
Permissions should be narrow and time-bound. A ticket agent might read support records but not export the customer table. A code review agent might inspect a repository but not deploy to production. A finance agent might prepare a payment file but need approval before sending it.
Zero trust adds another useful rule: verify each request instead of trusting the agent because it passed an earlier login. Check the agent identity, delegated user, requested tool, data classification, current risk, and task context. Short-lived credentials are safer than keys embedded in prompts or configuration files.
Teams often start with a broad role because it makes development faster. That choice becomes hard to unwind once workflows depend on it. Before production release, put scope, ownership, data access, testing, and rollback decisions next to each other in one place.
The trade-off is less convenience during early builds. That is a good trade. A short delay at a permission boundary costs less than tracing a compromised service account across several systems.
4. Tool and API Controls, Stop Unsafe Actions and Insecure Output Handling
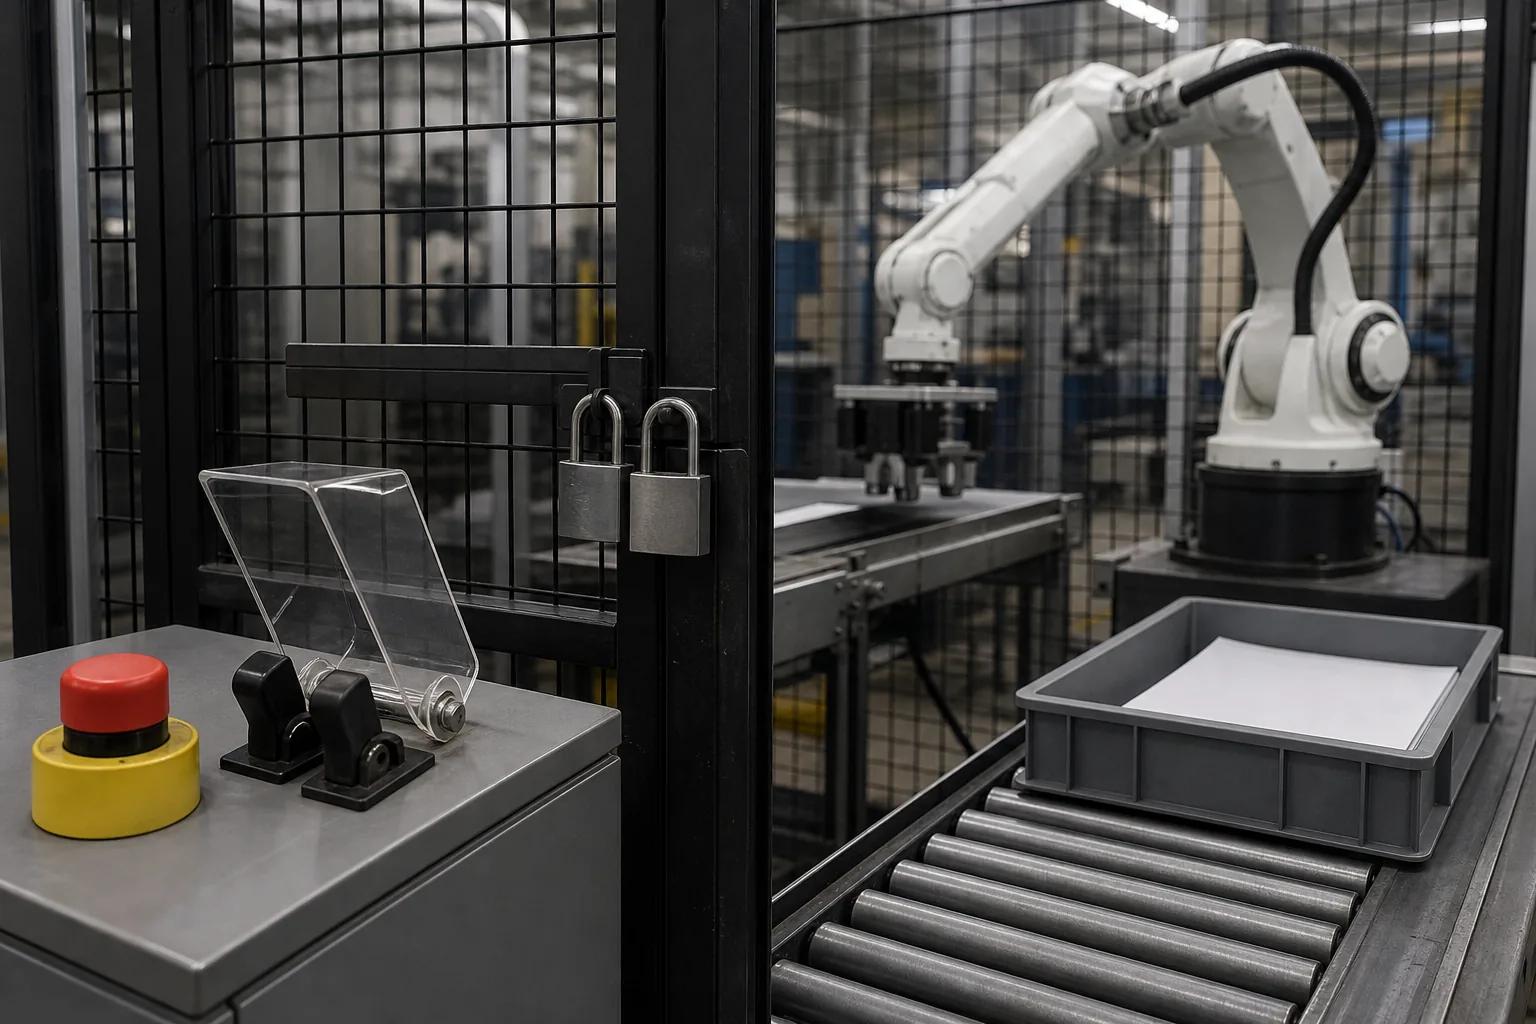
Tool controls decide what an agent can do after it has formed a plan. They are separate from prompt rules. An agent can misunderstand a valid request and misuse a legitimate API, so each tool needs its own boundary.
Start with a small tool set. Give each function a clear name, narrow parameters, and a defined failure response. A tool that accepts a free-form command creates more risk than one that accepts a validated record ID and a fixed action.
Use schema validation before execution. Reject unknown fields, unexpected data types, oversized requests, and dangerous parameter combinations. Add rate limits so a loop can't send thousands of messages or consume a costly service.
Output handling needs the same care. Never pass model output straight into a shell, database query, browser action, or customer message. Parse it into a known structure first. Then apply business rules and authorization checks.
- Use approval gates for transfers, deletion, bulk messaging, and access changes.
- Separate read tools from write tools.
- Log the input, selected tool, parameters, policy result, and final outcome.
- Return safe errors that don't expose secrets or internal system details.
For high-impact actions, constrain autonomy. Require human approval for financial transfers or bulk messaging, and use structured output formats and schema validation. A simple approval box isn't enough if the reviewer can't see the target, scope, and expected effect.
One useful decision rule is this: if an action would require a person to pause and check the details, the agent should pause too.
5. Sandboxing and Containment, Isolate Execution with Docker, VMs, and Canaries
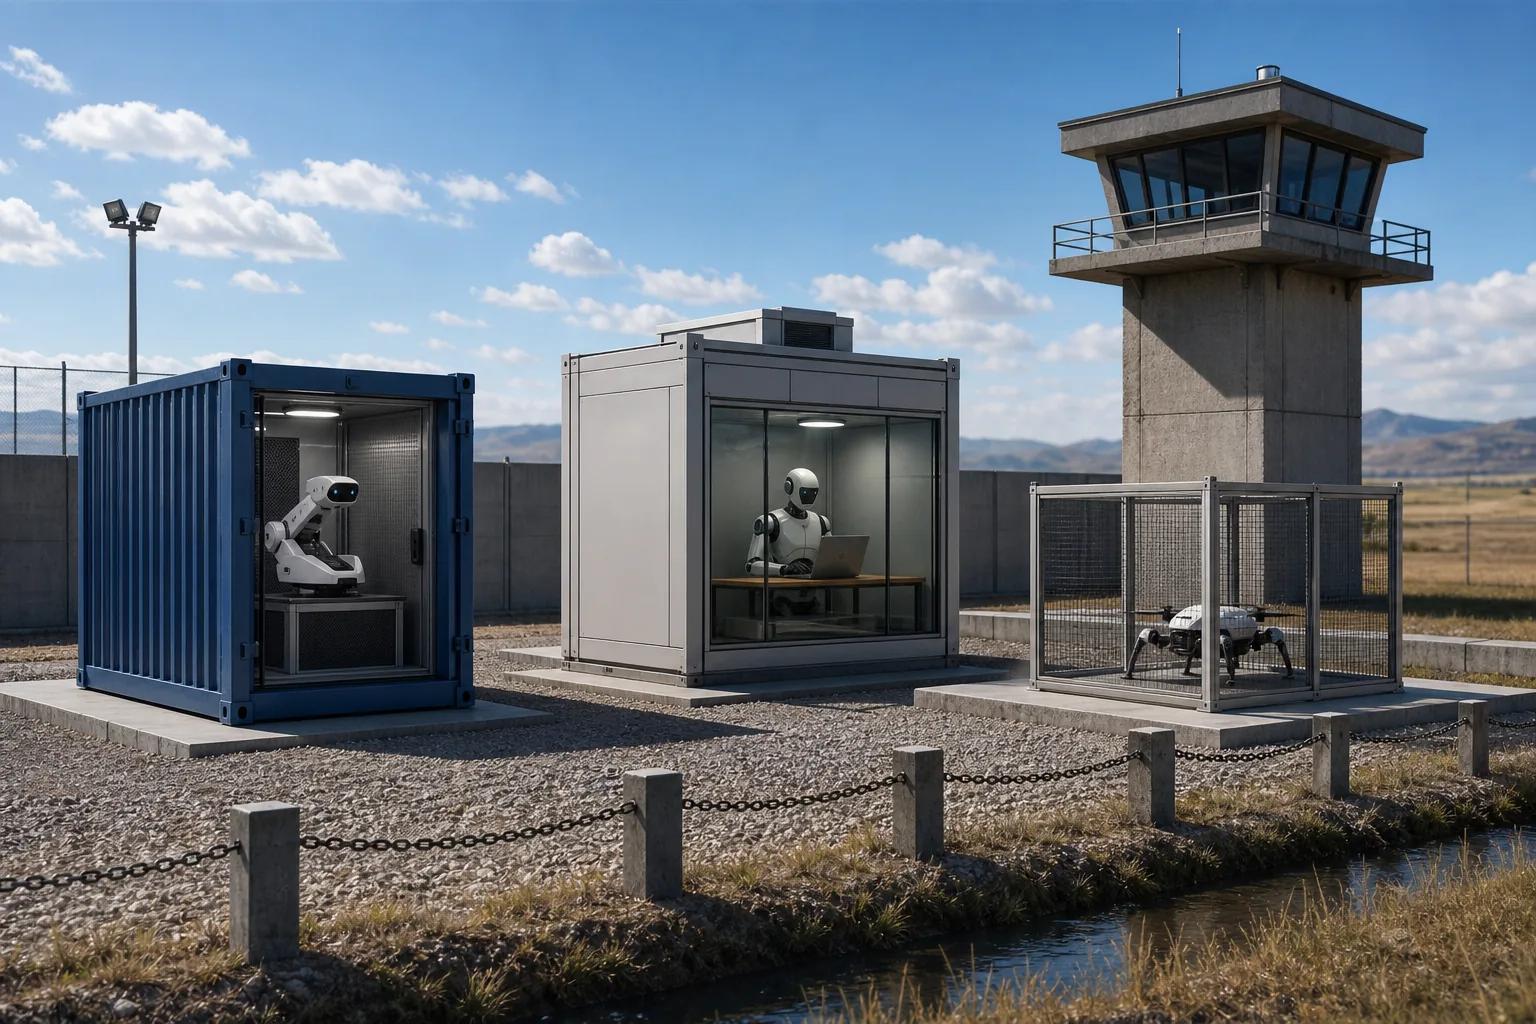
Sandboxing keeps an agent's code and files away from systems it doesn't need. It matters most when an agent can write code, run commands, process uploads, or use third-party tools.
A container can provide a useful boundary, but it isn't a complete security plan. Restrict the container's network paths. Mount only the files it needs. Drop extra operating system privileges. Block access to cloud metadata services unless there is a clear reason to allow it.
For higher-risk work, use stronger isolation such as a virtual machine or a dedicated execution worker. Keep secrets outside the runtime. The agent should receive permission through a broker or scoped token, rather than reading a long-lived key from its file system.
Canary releases help with changes to models, prompts, tools, and policies. Send a small amount of traffic to the new version. Compare its tool calls, data access, error rate, and approval requests with the known version. Stop the release if the action pattern shifts.
Long-lived, stateful agent workloads may need a persistent identity and scratch space while still requiring isolation and controlled suspension. Teams planning cloud deployment can also review cloud service considerations for security, migration, and compliance when comparing infrastructure choices.
Containment is not only for hostile agents. It also limits ordinary mistakes. If an agent loops, writes the wrong file, or follows a poisoned instruction, the blast radius stays small.
6. Runtime Monitoring, Detect Behavioral Drift, Rogue Agents, and Anomalous Actions
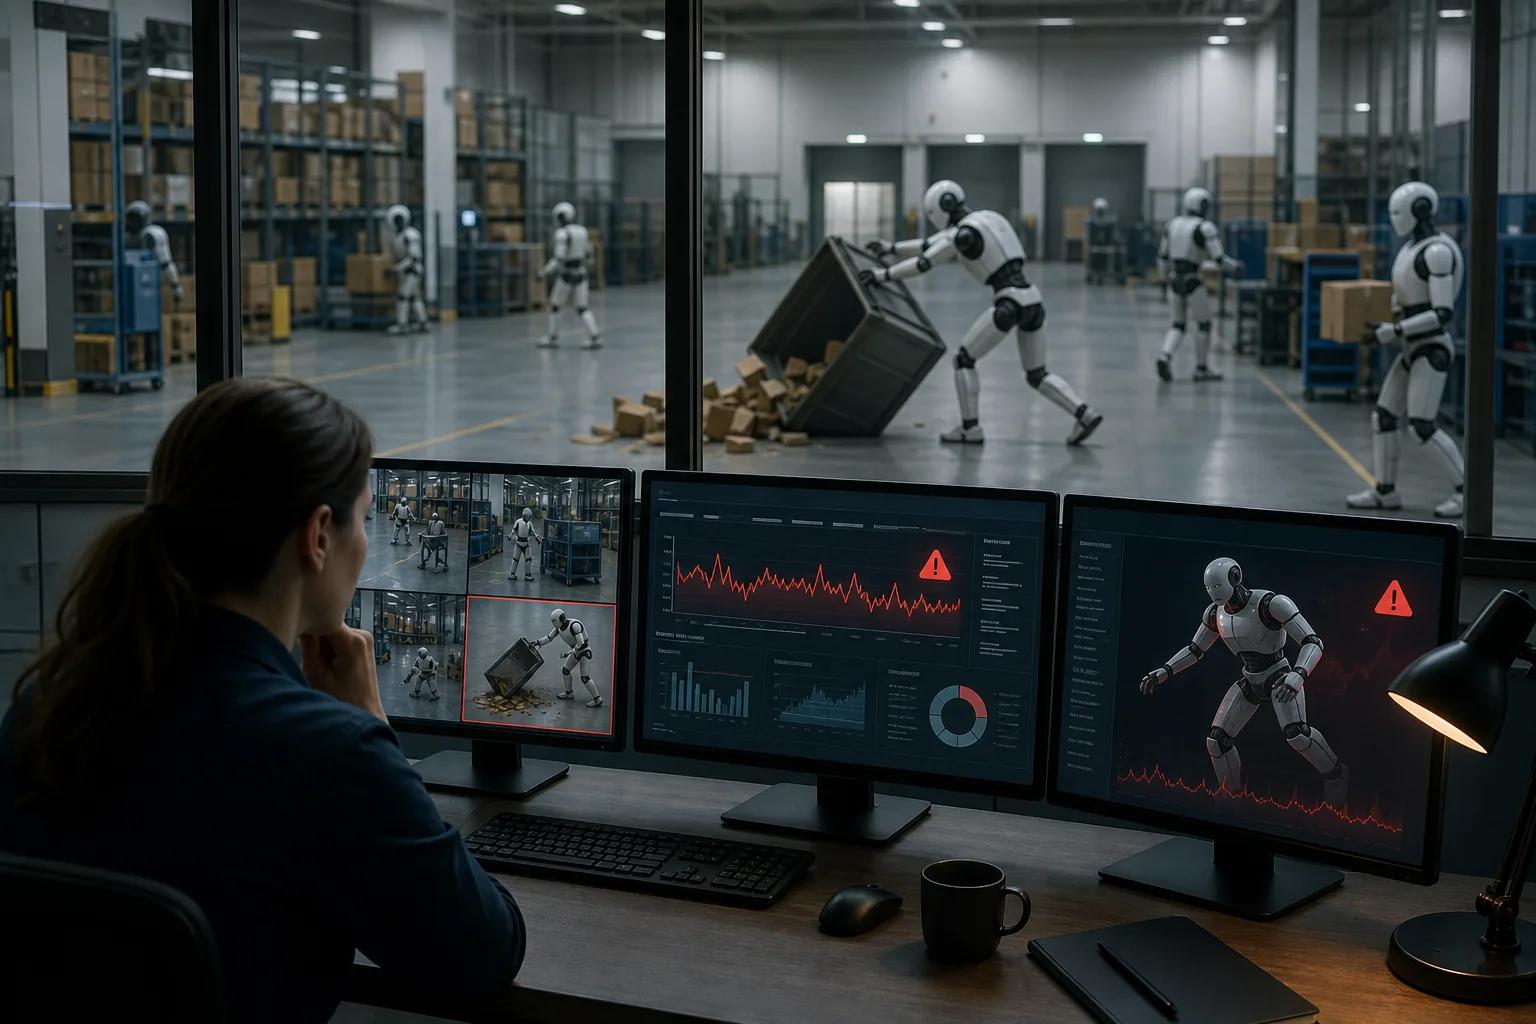
Runtime monitoring shows what the agent actually does, not what its design document says it should do. This is a core AI agent security consideration because agent behavior can change with the prompt, retrieved data, model version, or tool response.
Log each meaningful action as a connected trace. Capture the initiating identity, user authority, model version, prompt or prompt ID, retrieval source, memory write, tool call, policy decision, and result. Correlation IDs let investigators follow one task across several services.
Watch action chains instead of isolated events. A database read may be normal. An outbound request may also be normal. The combination of an unusual table read followed by external data transfer is more useful than either event alone.
Drift can be gradual. A support agent may slowly start querying records outside its normal scope. A coding agent may begin using a new endpoint after a plugin update. A monitoring system should compare behavior with the agent's stated purpose and permitted action graph.
Security teams should add signals for privilege use, data movement, tool selection, and approval bypass attempts.
Don't rely on an alert score alone. Give responders a kill switch, a credential revoke path, a way to freeze memory writes, and a rollback target. Detection without a response path leaves the agent active while people investigate.
7. Data Privacy and Credential Protection, Prevent Leakage from Stores, Vectors, and Metadata
Data leakage can happen through an answer, a log, a retrieval result, a vector store, or a tool request. AI agent security considerations must cover every place data travels, not only the model provider.
Classify data before it enters an agent workflow. Mark personal data, payment data, health data, trade secrets, credentials, and internal-only material. Then set rules for which agents may read each class and where that data may go.
Vector databases need the same care as source documents. Embeddings can preserve information about the content used to make them. Apply access checks before retrieval, not after the model has already received the result. Remove stale embeddings when the source record is deleted or access changes.
Keep credentials out of prompts, memory, logs, and tool output. Use a secrets manager or a credential broker. Give the agent a short-lived capability for one approved action, then revoke it when the task ends.
Metadata deserves attention too. File names, table names, account IDs, error messages, and URL paths can reveal more than a team expects. A harmless-looking trace may expose a customer name or an internal host to anyone with log access.
Data security work needs a clear owner. At Zylo Technologies, we treat classification, encryption, permission checks, and monitoring as parts of the same system. Teams can formalize those controls across the agent's data path with data security and encryption controls.
Privacy rules also depend on the use case and jurisdiction. Keep a record of what data the agent processes, why it needs the data, where processors receive it, and how long the system retains it.
8. AI Supply-Chain Security, Vet Models, Plugins, Prompts, Packages, and Components
An agent's supply chain includes more than application code. It may include a model, prompt template, retrieval index, plugin, package, tool schema, MCP server, container image, and another agent loaded at runtime.
Each component needs an owner and a version. Pin dependencies where possible. Verify package and image integrity. Scan the build. Keep a software bill of materials for the serving stack and the tools that can change agent behavior.
Prompt templates need version control too. Store the approved version. Record who changed it and why. Test the new version against injection, data access, tool selection, and output cases before release.
Dynamic loading creates a special risk. A new plugin can add a tool that the original threat model never covered. A changed tool description can alter how the model selects an action. A poisoned retrieval source can influence every future task.
Use a review gate for new components. Ask:
- Who owns this component?
- What data can it access?
- What code can it run?
- What identity does it use?
- How will the team revoke it?
- Which tests prove that its behavior stays within scope?
Supply-chain controls should continue after launch. Monitor changes to models, plugins, prompts, packages, and agent-to-agent routes. If a component changes outside the approved path, freeze deployment and investigate before the next task runs.
9. AI Governance and Shadow-AI Controls, Manage Compliance, Posture, and Hidden Agents
Governance turns security rules into operating practice. It answers which agents exist, who owns them, what data they touch, what controls apply, and when someone must review them.
Start with an inventory. Shadow AI creates blind spots when teams deploy agents without security review, logging, or a named owner. Discovery should include code repositories, cloud accounts, SaaS tools, automation platforms, service accounts, and network traffic.
Publish an approved tool list. Block unsanctioned AI domains where policy allows. More importantly, give teams a sanctioned path that is easy enough to use. A policy that only says “don't use this” will push work into less visible channels.
A governance record should include:
- Business purpose and accountable owner.
- Model, prompt, tools, data stores, and external processors.
- Risk tier based on the effect of an error.
- Required human review and escalation rules.
- Test evidence, monitoring coverage, and rollback method.
- Retention, deletion, and incident response requirements.
AI security posture management brings these records together with findings from cloud, identity, data, and runtime systems. It should show the difference between an approved agent and an unknown one, not only list technical alerts.
Governance is a living operating process. The practical discipline described in AI agent governance best practices is to review the agent after a material change, not file one approval document and forget it.
Compliance is part of the design, but a compliance label does not prove that an agent is safe. Map each obligation to an actual control, owner, test, and piece of evidence.
10. Resilience and Human Trust Controls, Contain Overload, Cascading Failure, and Social Engineering
Resilience controls keep one bad decision from becoming a system-wide event. Agents can call one another, retry failed tasks, reuse memory, and act faster than a human review queue can respond.
Human review must be designed well. A person who sees only “Approve action?” will approve too quickly. Show the requested action, target, data involved, reason, tool permissions, and material changes from the normal pattern.
Trust can also be exploited through confident language. An agent may sound certain while acting on weak evidence. Require independent confirmation for sensitive requests, especially when the request changes payment details, access rights, or customer records.
Use a kill switch that stops new actions and prevents queued work from restarting. Keep a separate recovery path for the operator. If the agent controls part of a physical or safety-sensitive process, use rules grounded in the environment rather than letting the model act as the only decision authority.
For teams building broader workflow automation, a review of AI workflow automation tools can help separate simple task flows from systems that need agent-specific limits. The more autonomy a workflow has, the more important its pause, retry, and recovery rules become.
| Risk pattern | Control to require | What the team should watch |
|---|---|---|
| Runaway loops | Step limits, timeouts, and rate limits | Repeated calls, rising cost, stalled completion |
| Cascading agent failure | Dependency caps and circuit breakers | One failure spreading across workflows |
| Unsafe approval | Show evidence and require independent review | Fast approvals without source checks |
| Resource overload | Budgets, queues, and backpressure | Concurrency, token use, and API saturation |
| Social engineering | Verify identity and intent outside the model | Urgent requests, authority claims, unusual exceptions |
FAQ
What are the main AI agent security considerations?+
The main AI agent security considerations are prompt injection, excessive permissions, tool misuse, data leakage, supply-chain changes, weak monitoring, shadow AI, and cascading failure. Start with three controls: least-privilege identity, strong input and output checks, and action-level monitoring. Then add sandboxing and human approval for high-impact actions.
How do you prevent prompt injection in AI agents?+
You prevent prompt injection with layered controls rather than one system prompt. Treat retrieved text as untrusted data, separate it from trusted instructions, test indirect attacks, validate tool parameters, and block or review sensitive actions. The agent should recheck its goal before execution because a successful attack may change the objective without changing the agent's tone.
Why is least privilege important for AI agents?+
Least privilege limits the damage an agent can cause after manipulation, error, or credential theft. Give each agent its own identity and only the permissions needed for its task. Prefer short-lived access. Separate read from write rights, and require added approval for deletion, payments, access changes, and bulk communication.
Should AI agents run in a sandbox?+
Yes, agents that execute code, process uploads, or handle untrusted tools should run in an isolated environment. Use restricted containers for lower-risk work and stronger isolation when the agent can reach sensitive systems. Limit network access, file mounts, operating system privileges, and cloud metadata access. Sandboxing reduces blast radius but doesn't replace access control.
How do you monitor an AI agent in production?+
Monitor the full action chain, not only model responses. Record the initiating identity, model and prompt version, retrieved data, memory writes, tool calls, policy decisions, outputs, and system changes. Alert on unusual combinations such as sensitive reads followed by external transfer. Keep a kill switch, credential revoke path, and rollback version ready.
Conclusion
Build AI agents as controlled software systems, not as prompts with broad access. Start with one narrow workflow, map every identity and tool, add approval at high-impact points, and test the design against hostile input before release. Zylo Technologies can help your team turn that model into a durable production system, and the next useful step is to review your current agent before it gains more autonomy.
Share this article
Author information coming soon.