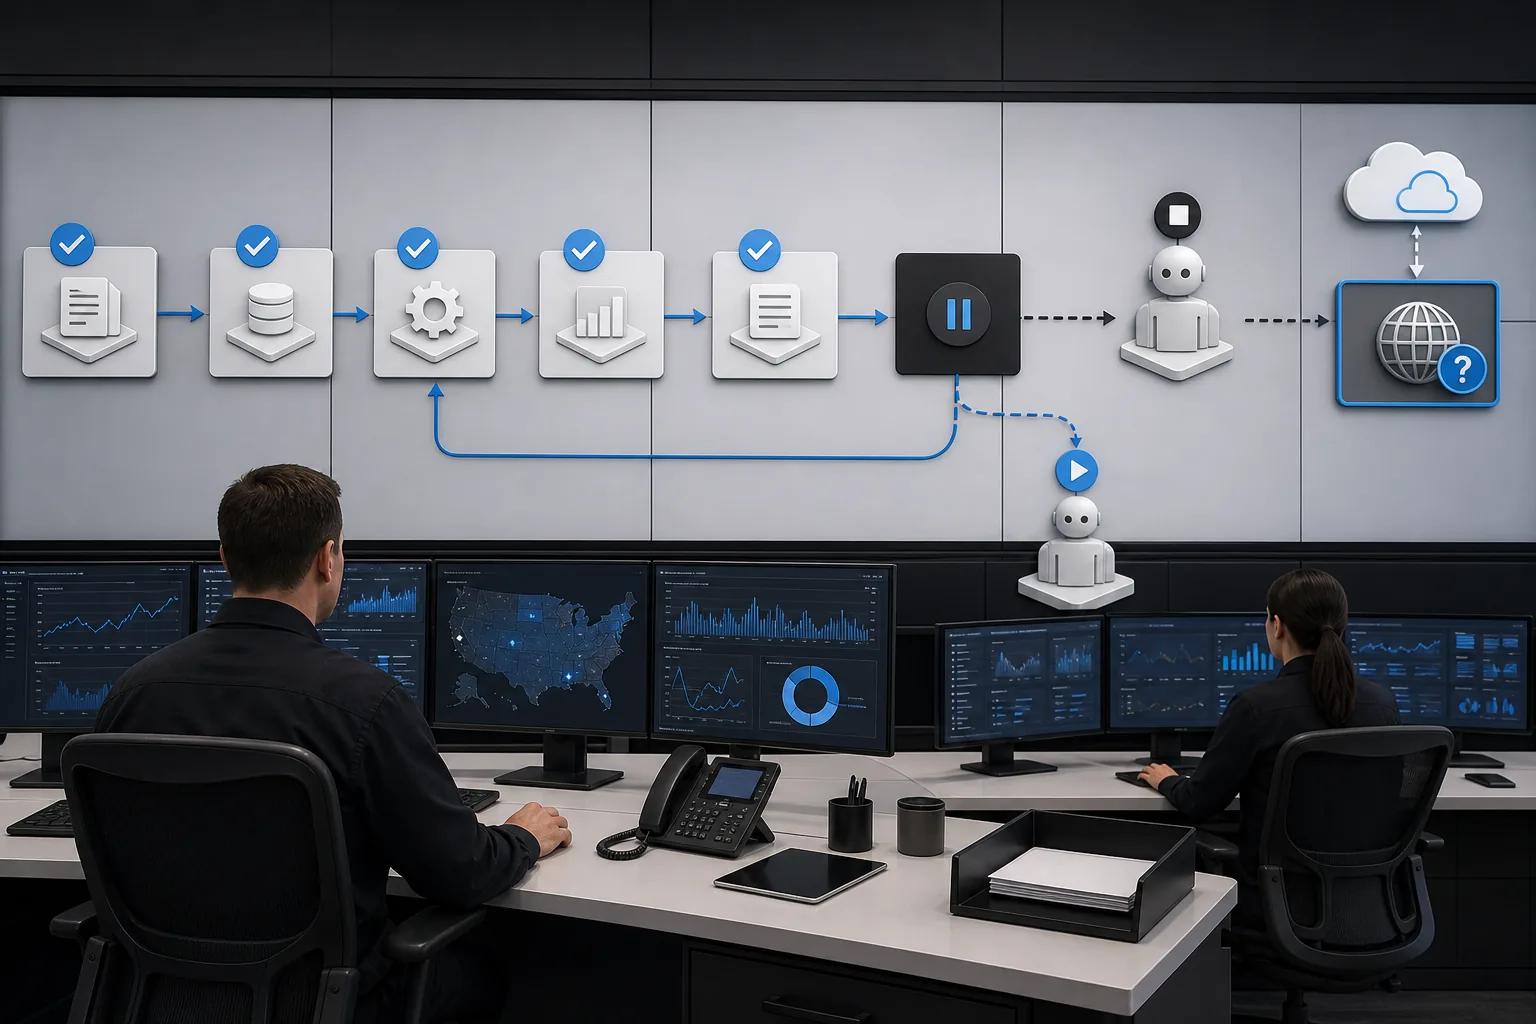
An agent can be right about what to do and still fail when its worker stops halfway through. Durable execution for AI agents records enough workflow progress to resume safely, without confusing saved chat history with proof that a business action happened.
We analyzed 25 comments and questions from Reddit and Quora about durable execution for AI agents and found that 28% mentioned state persistence mechanisms.
We’ll focus on the parts that make long-running work recoverable: state, checkpoints, retries, side effects, approval pauses, and recovery tests. The key design rule is simple: your application must know what happened before it asks an agent to continue.
What durable execution for AI agents actually means
Durable execution is a way to save workflow progress so a task can continue after a crash, restart, or long wait. The saved record tracks the run’s control state, such as its current step and completed work. It gives a new worker a reliable place to pick up.
That record is different from chat memory. Chat memory helps an agent use past messages as context. Execution history tells your application which steps ran, what they returned, and whether the workflow is still waiting or finished. A transcript can’t prove that an external system received a request.
For example, imagine an agent reviewing an invoice. It reads the document, checks the matching order, prepares a proposed correction, and waits for approval. Its durable state should show which checks passed, what correction is pending, and whose decision is needed. If the worker restarts, the next one can resume at the approval boundary instead of starting the review over.
We separate the workflow record from the model’s working context. The workflow record owns the current stage and permitted next actions. The model can help interpret an invoice, but it shouldn’t decide that an approval happened because the chat history sounds positive. Our AI agent architecture design guide explains how to map state and verification into the wider system.
A checkpoint is a saved point in that execution. It might hold a step result, a status, or a reference to an artifact. Checkpoints help, but they don’t define safe recovery by themselves. The workflow also needs rules for what can run again and how to verify actions outside the workflow.
Durable workflows can save execution state after steps and use it to resume interrupted work. The useful principle is broader than any one framework: save the details a replacement worker needs, not just a vague label such as “in progress.”
Key Takeaway
Chat memory helps with context; durable execution history helps the application decide what can safely happen next.
Where AI agent workflows fail, and what persistence can fix
Long-running workflows tend to fail at handoffs. A worker can stop during a deployment, an API can time out after accepting a request, or a person can take hours to approve a proposed action. In each case, the next worker needs to know what finished and what remains uncertain.
Persistence helps recover work that would otherwise live only in process memory. But a saved checkpoint doesn’t reveal whether a tool call changed an outside system. If an agent submits a customer update and the response gets lost, blindly repeating the request may create a duplicate or overwrite newer information.
Separate the workflow’s own progress from each external action. Record the action’s stable identifier, its inputs, the attempt status, and the response if one arrives. After a timeout, treat the result as uncertain until you check the destination system or safely repeat the same request.
Consider a customer-service agent that drafts a refund request. It can save the case details and its recommendation, then pause for a staff decision. If the worker fails while waiting, the workflow should resume with the same request and approval status. It shouldn’t generate a fresh proposal and quietly send it.
Persistence also supports useful recovery choices. A failed read may be safe to retry. A request that might have sent an email needs a status check or duplicate guard. A conflicting record may need a person to review it. For workflows that pass work between agents, each handoff needs a durable record of the task and the result expected back.
The distinction between a retry and a replay matters. A retry repeats an operation that failed or timed out. A replay rebuilds workflow progress from stored history. Either can go wrong if the workflow repeats a side effect without checking what already happened. That’s why we cover recovery boundaries in our guide to building AI agents that last.
Persistence doesn’t fix a bad decision or make an unsafe action acceptable. It gives the system a record from which to recover, investigate, or stop. When the record can’t establish whether an action succeeded, pausing for review is safer than marking the run complete.
How state, retries, and tool calls fit together
State, retries, and tool calls work as one system when every step has a defined input, outcome, and next transition. The workflow record holds the current status. A step attempt records what the worker tried. A tool call carries the action into another system.
Start with a stable run ID and a versioned workflow state. Save the current step and its inputs before work begins, then record the result before advancing. Store large files separately and keep stable references in the run record. This helps a replacement worker load the right evidence without relying on its predecessor’s memory.
For each tool call, decide whether repetition is safe. A read-only lookup is often safe to retry. A write should use an idempotency key, a stable identifier that lets the receiving system recognize repeated requests as the same intended action. If the receiver doesn’t support that pattern, check its current state before sending again.
Don’t promise exactly-once effects just because the workflow engine saves history. The workflow can coordinate its own progress, but it can’t always know what happened inside a separate service after a connection breaks. In many systems, the safer goal is at-least-once delivery with deduplication or verification at the destination.
For example, before creating a support ticket, the workflow can store a request ID tied to the run. If it loses the response, it can query the ticket system by that ID before trying again. If no matching ticket exists, it can retry. If one exists, it records that result and moves on.
Keep session context separate from the execution record. The model may need a concise summary to reason about the task, while the workflow needs structured facts such as the approved proposal ID or the last tool result. Our AI agent architecture best practices guide covers how to keep these boundaries clear.
Whatever framework you choose, test how it replays code and handles side effects before connecting it to live systems.
Pro Tip
For each write tool, document what makes a repeat safe and how the workflow checks for success after a timeout.
How to keep agent autonomy inside safe operating limits
Use a durable pause before actions that are hard to reverse. The agent can prepare a proposal, but a policy check or authorized person should approve the exact action before the workflow commits it. Approval after the action is only a review, not a control.
Represent the pause as a workflow state, not as a sleeping process. Save the proposed action, the evidence behind it, the person or role allowed to review it, and the decision status. When approval arrives, the worker should reload that state and confirm the decision still matches the pending action.
This check prevents a stale approval from authorizing a changed proposal. If the agent updates the amount, recipient, or record after approval, the old decision should no longer apply. Store a stable proposal version or digest so the workflow can compare what was approved with what it’s about to execute.
Separate low-risk work from actions with higher impact. An agent might classify a request or draft a reply without approval. Sending that reply, changing a production record, or initiating a payment may need a review step. The right boundary depends on your own policies and the cost of an error.
Make approval easy to act on. Present the proposed change beside the source facts that support it. Give the reviewer a clear way to approve, reject, or request edits. If no response arrives by the agreed deadline, keep the run paused or route it for follow-up. Don’t treat silence as consent.
We build custom AI agents at Zylo Technologies with durable architecture and client ownership in mind. That means the workflow rules, state, and decision rights should be clear to the team that will operate them. Senior-only delivery pods are part of Zylo’s model, but the approval policy itself must come from your business owners.
Set hard limits around the action path. Cap attempts for a step, stop after repeated errors, and define which cases require a person. These limits prevent a retry loop from turning a temporary service issue into a stream of repeated writes or messages.
For deeper boundaries around tools and stop rules, our AI agent implementation guide can help your team define the job before connecting it to business systems.
How to measure reliability before expanding an AI agent
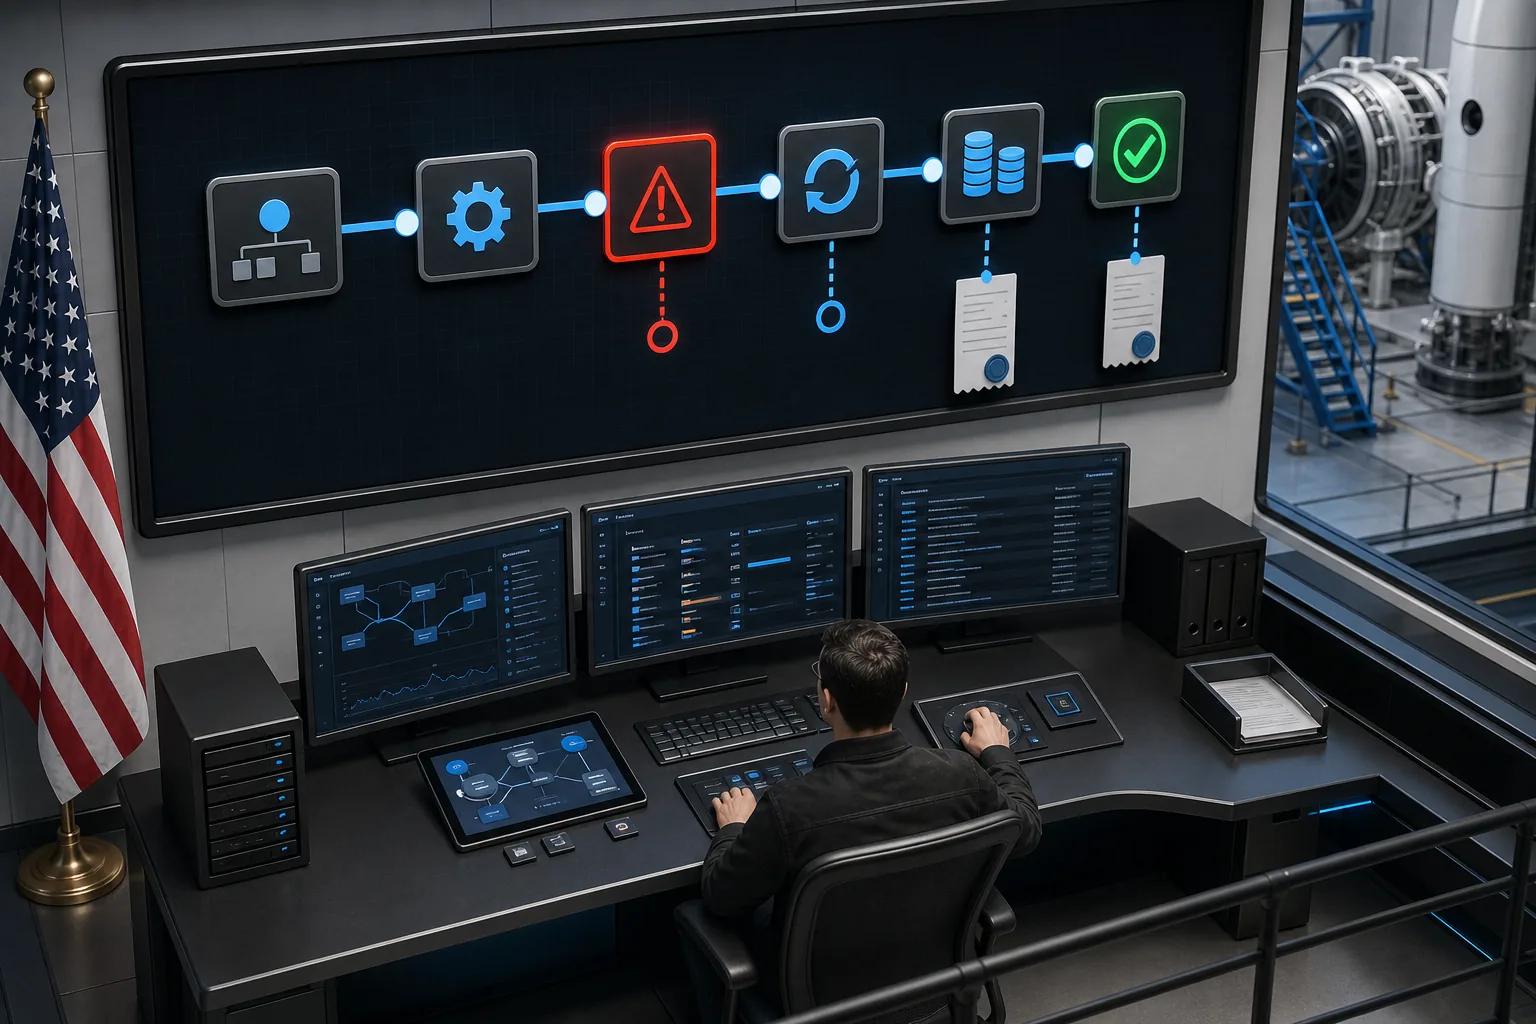
Measure whether the workflow reaches a verified business outcome, not only whether the model returns a response. A run can finish without an error and still leave a ticket unchanged or an approval attached to the wrong proposal.
Track a small set of workflow-level signals: completed runs with verified outcomes, runs that need human intervention, recovery success after interruption, and duplicate side effects. Also track retry counts and time spent waiting for approval. These measures show where the workflow breaks, not just whether the service is up.
Keep execution history separate from ordinary observability. Logs and traces help an operator inspect what happened across services. The durable workflow record controls what should happen next. An observability trace may help explain a missing response, but it isn’t a substitute for a saved approval or step result.
Each run should have a trace or correlation ID that connects model calls, tool attempts, state changes, approvals, and verification. Record the step outcome and timing. Redact secrets and sensitive content that an operator doesn’t need to investigate the run.
Test recovery on purpose before expanding access. Stop a worker after it saves a checkpoint. Stop it after a tool accepts a request but before the response returns. Restart it while it waits for approval. For each test, confirm that it resumes at the intended point and doesn’t repeat an unsafe action.
Use a fake downstream service for early tests. Make it return success, reject a request, or accept a request while simulating a lost response. Then inspect the durable state and the external record together. This exposes the uncertain outcomes that a simple happy-path test misses.
Our AI agent performance metrics guide can help define broader quality and cost measures. For durable execution, keep the test focused on one question: can a new worker establish what happened and continue without guessing?
Expand one workflow at a time. Start with a narrow action set and a clear owner who can review failed runs. Increase autonomy only after recovery tests pass and the outcome measures hold up under ordinary failures.
FAQ
What is durable execution for an AI agent?+
Durable execution records an agent workflow’s progress so it can resume after a failure or pause. The record should include the current step and the results needed to continue. It’s separate from chat memory, which gives the model conversational context but doesn’t prove that a tool action or approval occurred.
Does a checkpoint prevent duplicate tool calls?+
No, a checkpoint alone doesn’t prevent duplicate tool calls. It records workflow progress, but a timeout can leave the system unsure whether an external service completed the request. Use idempotency keys when supported, or check the destination system before retrying a write.
How should an AI agent handle a human approval pause?+
Save the proposed action and mark the workflow as awaiting approval. When a decision arrives, reload the saved state and confirm the approval applies to that exact proposal. Continue only after that check passes. If the proposal changes, ask for a new decision rather than reusing an outdated approval.
What should we test before expanding an agent workflow?+
Test a worker restart at different points, including after an external service may have accepted a request. Also test a failed tool call and a long approval wait. Check that the workflow resumes from the right state, avoids unsafe repeats, and records evidence that the intended business outcome occurred.
Conclusion
Build the workflow record before adding more autonomy. Start with one long-running process, define its safe retry rules, and test a restart at the point where an external action could have happened. If your team needs help designing or shipping that system, Zylo Technologies can work with you to map the recovery path before production use.
Share this article
About the author
AI Transformation Leader | Founder of Zylo Technologies | Helping businesses unlock value through AI.
Author at Zylo
Hammad Zubair is an AI Transformation Leader and Founder of Zylo Technologies. He helps businesses discover practical AI opportunities that reduce costs, improve efficiency, and accelerate growth. Through AI readiness assessments and transformation strategies, he enables organizations to identify high-impact automation and AI implementation opportunities.